AI Product
Evaluating AI Agents in Production: Golden Datasets, Human Review, and Release Gates
Connect representative test cases, slice-level metrics, reviewer evidence, and release gates to decisions about agent autonomy.
On this page
- Autonomy is earned, not configured
- Start from the customer failure mode
- Offline evals: make regressions boring
- What good golden sets look like
- Online metrics: the product’s truth
- HITL UX is part of the model system
- Policy gates beat prompt pleas
- Model-graded evals: use carefully
- Shipping cadence that protects trust
- Connecting evals to product discovery
- A concrete example shape
- Anti-patterns
- Ownership after launch
- Closing
- A release gate that is inspectable
- A local retrieval evaluation, including its limits
- Further reading
The fastest way to burn an AI product is to confuse model fluency with product readiness. Fluency ships demos. Trust ships businesses.
I treat evals and human-in-the-loop (HITL) as core product engineering — not a research nice-to-have. This article describes an evaluation approach. The examples are design patterns, not reported results from a deployed evaluation run.
Autonomy is earned, not configured
A useful ladder:
- Assist — draft / suggest; human always commits
- Prepare — create pending objects; human approves
- Act in sandbox — side effects only in reversible environments
- Act with policy — narrow auto-actions with kill switches
- Broad autonomy — rare; requires strong evals + monitoring
Most 0→1 products should live in 1–2 for longer than founders want. That restraint is a feature.
If you cannot measure when the model is wrong, you cannot safely remove the human.
Start from the customer failure mode
Before writing an eval set, write the nightmare:
- Wrong owner assigned on a customer commitment
- Email sent with confidential data
- Fake “decision” becomes a roadmap item
- Medical / legal / financial hallucination phrased confidently
Your HITL boundary should sit directly in front of that nightmare. Everything else can be more automated.
Offline evals: make regressions boring
Minimum viable eval harness:
- Golden inputs — real anonymized samples, not toy sentences
- Expected structured outputs — JSON fields that matter to the product
- Graders
- schema validity (hard fail)
- exact / fuzzy match on critical fields
- citation presence
- refusal correctness when evidence is missing
- Baselines — last prompt/model that shipped
Run on every change to prompts, tools, routers, or packing logic.
Keep hard constraints separate from graded quality so a high average cannot mask a forbidden action:
def grade(candidate: dict, expected: dict) -> dict:
    evidence_ok = bool(candidate.get("evidence_ids"))
    schema_ok = set(candidate) >= {"title", "owner_id", "evidence_ids"}
    owner_ok = candidate.get("owner_id") == expected.get("owner_id")
    return {
        "hard_pass": schema_ok and evidence_ok,
        "owner_match": owner_ok,
        "needs_review": not (schema_ok and evidence_ok and owner_ok),
    }
This toy grader illustrates release logic; it is not a substitute for domain validation or an evaluation result. In a real harness, version the rubric and expected output, report each failure slice, and inspect false passes as well as false rejects.
What good golden sets look like
- Include ugly reality: interruptions, crosstalk, multilingual snippets, empty docs
- Label unknown cases where the correct behavior is to abstain
- Keep a “shark tank” set of historical production failures
- Version datasets like code
Quantity helps; representative failure diversity helps more.
Online metrics: the product’s truth
Offline scores can look great while users hate you. Track online:
- Acceptance rate — approved without edits
- Edit distance — how much humans rewrite
- Override reasons — taxonomy beats free text alone
- Time-to-approve — friction signal
- Escape rate — users abandoning the AI path
- Cost per accepted outcome
- Incident rate — severe wrongness classes
These metrics close the ownership loop after deploy. They tell you whether to widen autonomy or tighten the contract.
HITL UX is part of the model system
A review screen is not a form. It is a reasoning prosthesis:
- Show evidence next to claims
- Highlight low-confidence / changed fields
- One-click approve for clean cases; surgical edit for messy ones
- Capture why the human changed something (feeds the shark tank)
If review is painful, humans rubber-stamp — and you lose the safety you thought you bought.
Policy gates beat prompt pleas
Do not rely on “please be careful” in the system prompt for dangerous actions. Use deterministic gates:
- Allowlists of tools per workflow stage
- Max spend / max sends per run
- Required citations for external communication drafts
- Hard block on actions when schema validation fails
- Environment flags:
HITL_REQUIRED=trueuntil metrics clear a bar
Prompts suggest. Policies enforce.
Model-graded evals: use carefully
LLM-as-judge is useful for fuzzy quality (tone, summary usefulness). It is dangerous for factual correctness about your domain unless tightly constrained.
My stance:
- Deterministic graders for fields that must be right
- Model graders for subjective quality — with spot human audits
- Never let a judge silently become the only release criterion
Shipping cadence that protects trust
A release train I like for AI features:
- Shadow mode — model runs, humans don’t see it; compare offline
- HITL mode — model proposes; humans approve
- Partial auto — only high-confidence narrow actions
- Expand — when acceptance metrics hold for a defined window
Skipping steps is how “we’ll fix it later” becomes a churn event.
Connecting evals to product discovery
Customer requests often sound like capability asks (“auto-update Jira”). Evals help you renegotiate:
- If a representative evaluation shows assignee extraction is unreliable, the honest product may be propose assignees, not auto-assign.
- If reviewers regularly rewrite action items but accept summaries, invest in action-item evaluation and workflow design before adding a flashier chat UI.
This is AI product engineering: design the feature to the measured capability, then improve the capability with a feedback loop.
A concrete example shape
For meeting → tasks:
| Stage | Automation | Gate |
|---|---|---|
| Transcript normalize | Auto | schema |
| Candidate tasks | Auto | schema + evidence span |
| Task create in workspace | HITL | human approve |
| Notify channel | Auto after approve | idempotent send |
Evals focus on candidate quality and evidence linking. Online metrics focus on approval/edit rates. Autonomy expands only when both stay healthy.
Anti-patterns
- Evaluating only happy-path demos
- Using win-rate chatbots as product QA
- Hiding uncertainty to look “smart”
- No shark tank of past incidents
- Removing HITL because “the model got better” without metric proof
- Logging prompts with PII into eval sets carelessly
Ownership after launch
When feedback arrives, I want a path:
complaint → reproduce on golden/shark set → fix packer/prompt/tool/policy → eval gate → staged rollout
That path is the difference between a team that ships AI and a team that operates AI products.
Closing
Evals tell you what the system can do. HITL decides what the product is allowed to do today. Together they let you move from 0→1 without gambling the user’s trust for a demo metric.
If you are hiring for Senior AI Product Engineering, this is the muscle to interview for: not who can call the newest model API, but who can design capability contracts, prove them, and own the aftermath when reality disagrees.
A release gate that is inspectable
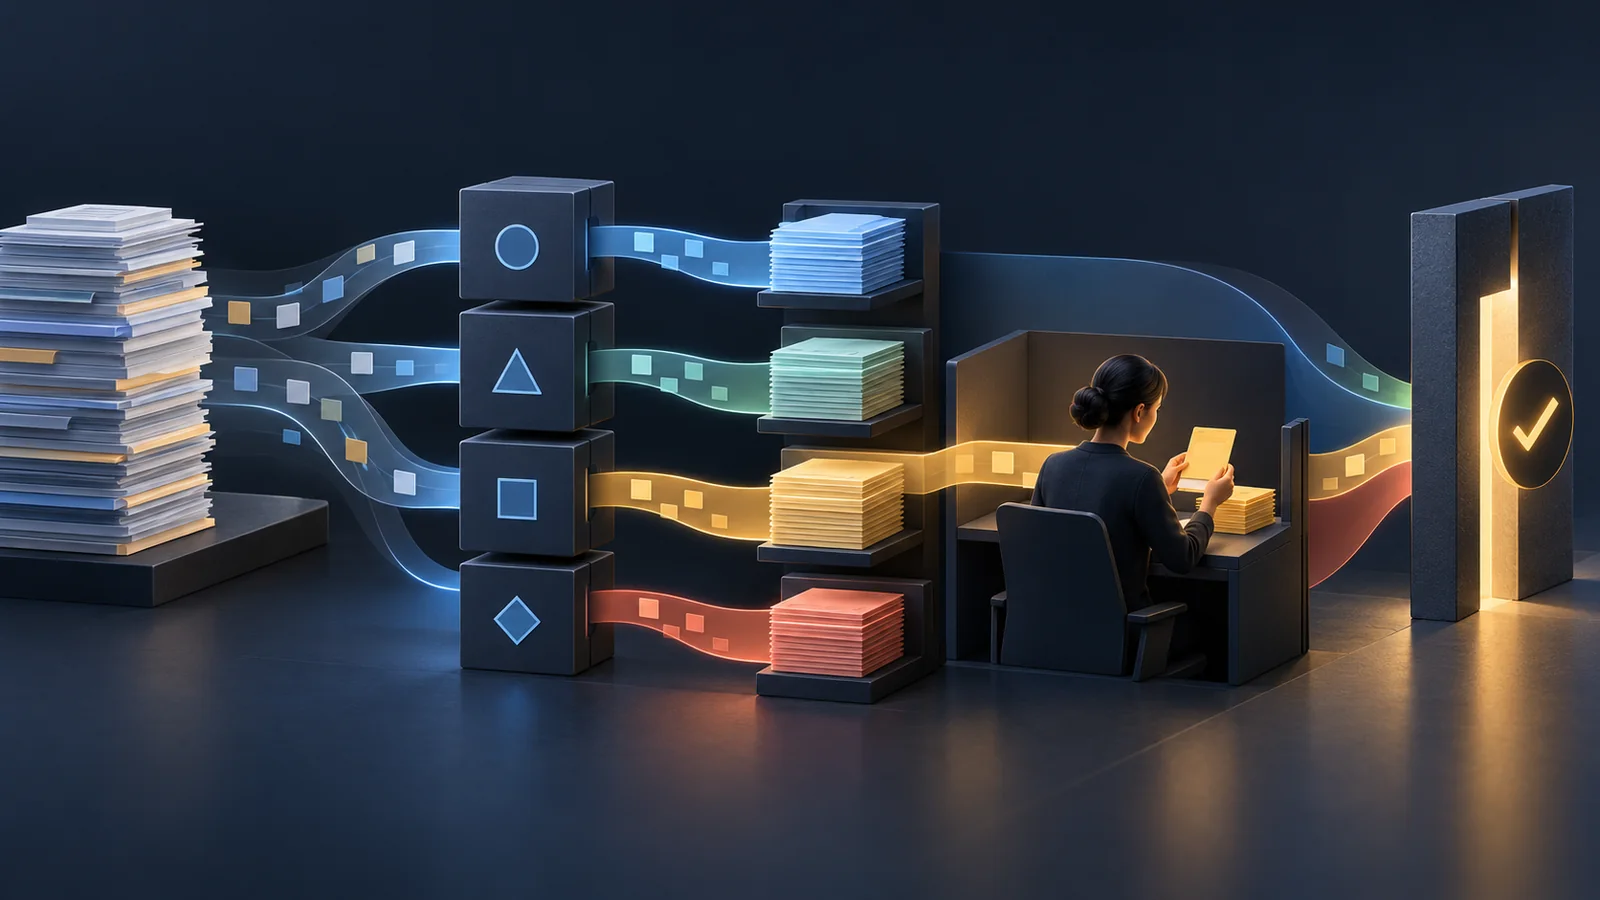
Keep release criteria small enough to explain and strict enough to block a regression. For example, a change can be held when any hard constraint fails (schema validity, authorization, evidence requirement), when a critical slice falls below its agreed baseline, or when review reveals a new severe failure mode. Track each slice separately; an aggregate average can hide a regression on a high-risk class.
Store the dataset version, model identifier, prompt/template version, tool versions, grader version, and run configuration with the result. Without those identifiers, a passing number cannot be reproduced. Protect evaluation data as carefully as product data: redact or synthesize personal content, limit access, and define retention.
Human review is also not a perfect label source. Reviewers can disagree, move quickly, or inherit the same bias as the model. Sample disagreements, document rubric changes, and treat release metrics as evidence for a decision rather than a proof of safety.
A local retrieval evaluation, including its limits
The ProfMe repository contains a document-retrieval evaluation report with a synthetic, non-sensitive corpus of nine manually labeled cases and deterministic embeddings. The local run records lexical Recall@5/Recall@10 at 0.333/0.333, semantic at 1.000/1.000, and hybrid at 1.000/1.000. Hybrid scope compliance is 9/9; top-1 citation correctness is 7/9.
Those numbers are useful because they suggest two separate gates: did retrieval find an in-scope relevant document, and did the returned answer cite the right item first? They are also deliberately narrow. The report says answer faithfulness and LLM-context inclusion were not measured, the test is local rather than staging or production, and the corpus is small. The result supports follow-up experiments, not a claim that users will receive correct answers at those rates.
query set + labeled evidence
            │
            ▼
lexical / semantic / hybrid retrieval
            │
            ├── scope compliance ──► correct workspace?
            ├── recall / ranking ──► relevant evidence retrieved?
            ├── citation check ────► answer points to the right source?
            └── faithfulness eval ─► answer supported by cited evidence?
                                      (not measured in this local run)
The next useful evaluation is not a bigger aggregate number by itself. It is a reviewed set of misses grouped by exact identifiers, paraphrase, scope, freshness, and contradictory history. Then add answer faithfulness and authorization tests to the same release decision. A human review queue is valuable when it exposes the evidence and uncertainty; it is not a substitute for measuring whether automation is safe enough for its intended action.
Further reading
Working on a Similar Engineering Challenge?
Designing release gates for an AI feature? I can help connect evaluation evidence to product decisions.
Satish builds AI-native applications, agent workflows, and scalable backend systems across retrieval, orchestration, integrations, product architecture, and reliability.
Related reading
- AI AgentsHow to Build Reliable AI Agents in Production: Architecture, Tools, State, and EvaluationWhat I learned shipping agent workflows end to end — from customer jobs and capability limits to tool graphs, state, evals, and post-deploy ownership.
- AI SystemsFault-Tolerant AI Agents: Retries, Checkpointing, Idempotency, and Durable WorkflowsDesigning durable AI workflows with checkpoints, idempotent tools, Temporal-style recovery, and human takeover — so partial failure does not become silent corruption.