AI Systems
Fault-Tolerant AI Agents: Retries, Checkpointing, Idempotency, and Durable Workflows
How to resume interrupted workflows safely with persisted progress, idempotent side effects, bounded retries, and explicit recovery states.
On this page
- Failure is the default timeline
- The recovery contract
- Checkpoints beat vibes
- Idempotency keys are product infrastructure
- Separate model failure from tool failure
- Sagas for multi-write workflows
- Human takeover as a first-class state
- Timeouts, heartbeats, and long work
- Poison messages and infinite loops
- Observability that enables recovery
- A pattern from durable extraction pipelines
- Testing recovery (do this on purpose)
- Product takeaway
- Recovery test matrix
- A durable workflow example from ProfMe
- Further reading
If your agent cannot survive a crashed worker, a timed-out tool, or a rate-limited model, it is not a product — it is a script with confidence. Production AI systems fail in the middle. The product question is whether failure becomes recoverable progress or silent corruption.
This is one of the least glamorous, most differentiating skills in AI product engineering: designing fault recovery before the first customer depends on the workflow.
Failure is the default timeline
Typical mid-flight failures:
- LLM provider 429 / 500 mid-tool-loop
- Tool succeeds but the process dies before persisting the observation
- Partial CRM update + incomplete follow-up email
- Duplicate retries create duplicate tasks
- Human closes the laptop during a long research run
If your mental model is “retry the whole job,” you will double-charge cards, spam users, and lose trust.
The recovery contract
Before implementation, I write a recovery contract for the feature:
- What is the unit of progress? (step, document, entity, meeting)
- What must be idempotent? (creates, sends, charges)
- What is safe to redo? (pure retrieval, classification)
- What requires human arbitration? (conflicting writes, low-confidence mutations)
- What does the user see while we recover? (status, last good checkpoint)
No contract → no production agent.
Checkpoints beat vibes
Durable execution patterns (Temporal, custom workflow engines, or carefully designed queues) share an idea: persist decisions at boundaries.
A practical agent step boundary:
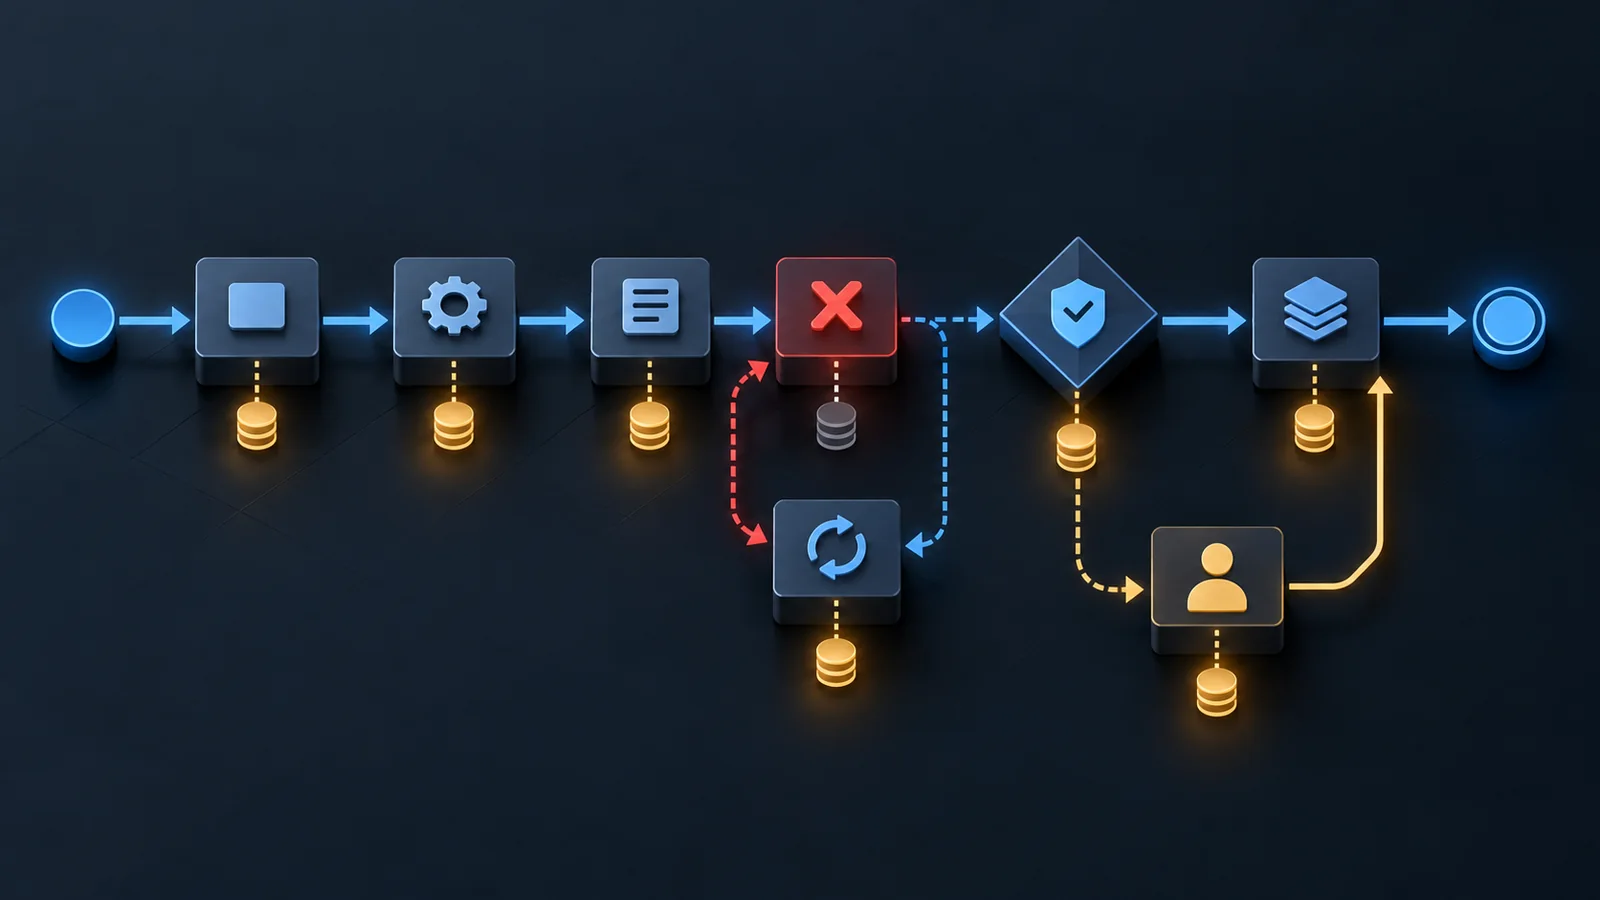
Load checkpoint
  → Decide next action (recorded)
  → Execute tool with idempotency key
  → Validate observation
  → Reduce into state
  → Persist checkpoint
  → Emit metrics
If you die anywhere after the tool but before checkpoint, replay must detect the tool already ran.
Idempotency keys are product infrastructure
Every side-effecting tool call gets a key derived from:
workflow_id + step_name + logical_input_hash
The tool adapter checks a ledger before executing. Retries become no-ops instead of duplicates.
An idempotency ledger needs a defined scope and a payload policy. Reusing one key with a different payload should normally be rejected, not treated as success:
key = hash(tenant_id, workflow_id, step_name, canonical_input)

if ledger[key] exists:
    if ledger[key].input_hash != hash(canonical_input):
        return conflict
    return ledger[key].stored_result

result = call_external_system(idempotency_key=key)
persist(key, input_hash, result)
This pseudocode leaves out transactional details. If the remote API does not support idempotency, a local ledger cannot eliminate the crash window between remote success and local persistence. Reconciliation or a human-visible uncertain state may be required.
That uncertain state deserves its own branch. A client timeout does not prove that a remote write failed; the request may have committed while its response was lost. Before retrying, query by the remote operation ID or the stable business key when the integration supports it. If neither lookup nor idempotency is available, pause for reconciliation instead of replaying a potentially destructive write. This trades some latency and operator work for a clear boundary against duplicate effects.
Idempotency is not an optimization. It is how you make “at least once” delivery compatible with customer trust.
Separate model failure from tool failure
Treat these differently:
| Failure | Recovery stance |
|---|---|
| Model timeout / malformed JSON | Retry with backoff; maybe fall back model; eventually needs_review |
| Tool auth error | Stop; alert; do not burn tokens guessing |
| Tool empty result | Continue with alternate strategy or ask human |
| Tool success, ambiguous meaning | Do not invent; mark uncertain fields |
| Budget exhausted | Checkpoint and pause; never silently truncate critical steps |
A common bug: catching all exceptions and “asking the model what to do.” That turns infrastructure errors into creative writing.
Sagas for multi-write workflows
When a workflow must touch multiple systems (DB + email + CRM), use compensating actions or staged commits:
- Write pending records in your DB
- Perform external mutations with idempotency
- Mark committed only when all required effects succeed
- On failure, compensate or leave pending for human ops
Never let the model be the distributed transaction coordinator. Models are bad at that. Workflow engines and ledgers are good at that.
Human takeover as a first-class state
needs_review is not a shame status. It is how products stay honest.
Design:
- Freeze side effects when confidence or budget thresholds trip
- Show the human the checkpoint, evidence, and proposed next action
- Resume from the same workflow ID — do not restart from zero
- Record the human decision as durable state for evals
This is end-to-end ownership: the system asks for help instead of improvising damage.
Timeouts, heartbeats, and long work
Long agent runs need liveness:
- Heartbeat while waiting on tools
- Soft timeouts per step; hard timeouts per workflow
- Progress events the UI can show (“retrieving sources… validating schema…”)
- Cancellation that leaves a clean checkpoint, not a half-write
Users will wait for async work. They will not wait without a signal.
Poison messages and infinite loops
Agents love loops. Guardrails:
- Max tool calls / max tokens / max wall clock
- Detect repeated identical actions
- Circuit-break a flaky tool after N failures
- Dead-letter workflows that exceed policy for ops inspection
If you only log “agent finished with error,” you will not sleep.
Observability that enables recovery
Logs that say LLMError are useless. I want:
workflow_id,run_id,step,attempt- Model + prompt version hashes
- Tool name + idempotency key + latency
- Checkpoint version
- Cost accrued so far
- Last human-visible status
With that, on-call can answer: resume, compensate, or kill?
A pattern from durable extraction pipelines
For meeting → structured professional memory style systems, Temporal (or equivalent) shines because:
- Audio/transcription/LLM extraction each can fail independently
- Activities are retried with backoff
- Workflow state remembers which stage completed
- Humans can approve derived tasks without reprocessing audio
The product outcome is boring in the best way: yesterday’s meeting still becomes today’s tasks even if a provider blinked.
Testing recovery (do this on purpose)
Chaos drills that actually help:
- Kill the worker mid-tool
- Return 500 from the model on attempt 1, success on attempt 2
- Make a tool succeed but delay the response past client timeout
- Replay the same workflow ID twice
- Force
needs_reviewand resume after human approve
If these are not in CI or staging playbooks, production will invent them for you.
Product takeaway
Fault recovery is how AI products earn the right to automate. Customers do not need perfect models. They need systems that:
- make partial progress durable
- avoid duplicate side effects
- ask for help when uncertain
- explain what happened when something breaks
That is 0→1 ownership after deployment: not only shipping the happy path, but designing the sad path so feedback and failures become iteration fuel instead of trust debt.
Recovery test matrix
For each side effect, test the boundary where its outcome becomes ambiguous:
| Injected failure | Expected invariant |
|---|---|
| Worker stops before the call | Retry may execute the action once |
| Remote system commits, response is lost | Retry uses the same remote idempotency key or marks outcome uncertain |
| Response arrives, local checkpoint fails | Replay retrieves the prior result or reconciles before another write |
| Retry budget is exhausted | Workflow pauses with visible state and a support path |
| Human approves after pause | Resume the same logical workflow without replaying completed effects |
These are proposed test cases, not results from a completed chaos test. A local fake integration can verify application behavior; it cannot prove that a vendor's API honors the same idempotency semantics under every failure.
A durable workflow example from ProfMe
The ProfMe processing workflow is a useful example of separating orchestration from domain work. The source defines named activities for transcription, extraction, ingestion, and related enrichment stages. It also contains explicit retry policies for bounded business work and for semantic-index batches.
workflow starts
     │
     ▼
activity: prepare evidence ──► checkpoint / persisted state
     │                                  │
     ▼                                  ▼
activity: extract candidate       retry after transient failure
     │                                  │
     ▼                                  ▼
activity: validate + ingest ◄── reconcile before repeating writes
     │
     ├── success ──► next named activity
     └── terminal failure ──► visible failure state / operator action
This is a pattern, not evidence that retries are automatically safe. A retry can repeat an email, create duplicate records, or overwrite newer information unless the activity uses an idempotency key, checks a durable result, or reconciles before writing. Similarly, the workflow’s retry schedule says what the coordinator will try; it does not show that every external provider or storage system will recover.
The repository’s local document-security report is explicit about what it did not test in staging: late worker writes after deletion against a cloud worker and some authorization edge cases. That kind of boundary belongs in an operational runbook. A passing local test can demonstrate the tested branch; it cannot close a cloud timing or identity gap that was outside the test environment.
Further reading
Working on a Similar Engineering Challenge?
Need a workflow that can recover safely after partial failure? We can work through durable execution and idempotent actions.
Satish builds AI-native applications, agent workflows, and scalable backend systems across retrieval, orchestration, integrations, product architecture, and reliability.
Related reading
- AI AgentsHow to Build Reliable AI Agents in Production: Architecture, Tools, State, and EvaluationWhat I learned shipping agent workflows end to end — from customer jobs and capability limits to tool graphs, state, evals, and post-deploy ownership.
- AI ProductEvaluating AI Agents in Production: Golden Datasets, Human Review, and Release GatesA practical playbook for offline evals, online acceptance metrics, HITL boundaries, and tightening autonomy only when the product earns it.