ProfMe
AI-Powered Longitudinal Professional Memory & Context Retrieval
A professional intelligence product designed to help high-context professionals recover critical commitments, decisions, and relationship nuance before and after conversations. Built with FastAPI, Temporal durable orchestration, hybrid lexical/vector search, and a staged extraction pipeline that eliminates hallucination contamination.
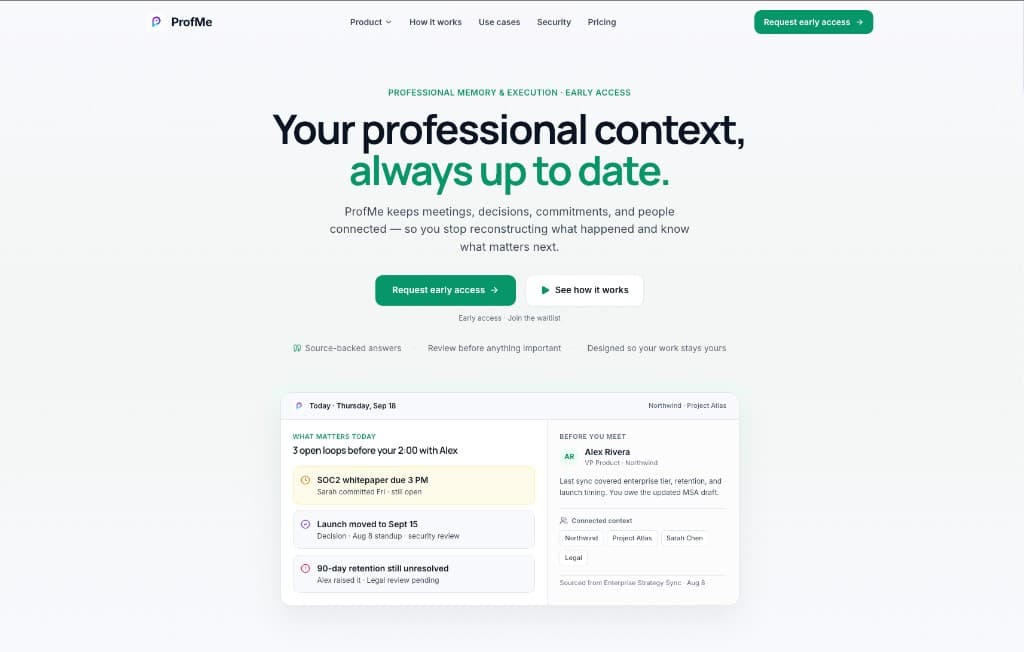
Table of Contents
- 01 — The Problem: The High-Context Productivity Drain
- The Conventional Workflow Breakdown
- 02 — Target Audience & Market Landscape
- Ideal Customer Profiles (ICPs)
- Competitor Landscape & Differentiation
- Market Sizing Framework (Bottom-Up)
- 03 — Product Strategy & Strategic Decisions
- 04 — System Architecture
- Key Architectural Boundaries
- 05 — Deep Engineering Challenges
- 06 — Testing, Verification & Security Boundaries
- Multi-Tenant Data Isolation
- 07 — Business Model & Go-to-Market Strategy
- Monetization Model
- Customer Acquisition Strategy
- 08 — Engineering Lessons & Future Priorities
- 09 — Related Case Studies & Technical Writing
Most AI meeting assistants treat transcripts as disposable text: you record a 45-minute call, receive a bulleted summary five minutes later, and the conversation vanishes into a siloed archive.
When you meet the same client three weeks later, you are back to square one. You cannot quickly answer the questions that actually dictate business outcomes: What did I promise Sarah? What technical decisions did we make regarding database migration? What open questions did we leave unresolved?
I designed and engineered ProfMe to solve this longitudinal context problem. Rather than treating meetings as isolated summaries, ProfMe treats conversations as an observational input stream to construct an accumulating, structured knowledge graph of a professional's working relationships.
01 — The Problem: The High-Context Productivity Drain
High-context knowledge workers—independent consultants, fractional executives, technical advisors, and solo agency founders—manage 5 to 10 distinct client relationships simultaneously.
The Conventional Workflow Breakdown
In an average week, a fractional CTO or management consultant conducts 15 to 25 meetings across different companies, stakeholders, and technical stacks:
- Meeting Capture: The professional takes rough notes in Notion or Apple Notes, or uses a bot-based transcription tool (Otter, Fireflies).
- Context Fragmentation: Action items are scattered across Slack threads, Google Docs, and email drafts.
- Pre-Meeting Scramble: Before a recurring client meeting, the consultant spends 10 to 15 minutes manually searching their inbox, reviewing past notes, and reading previous transcripts to remember context.
- Relationship Friction: If a commitment is forgotten or a past decision is re-debated, trust erodes and consulting leverage drops.
Generic AI summaries do not solve this. A 10-point summary generated immediately after a call tells you what happened in that room, but it fails to answer longitudinal questions across time:
- "Show me every commitment made to the engineering team across the last three sprints."
- "When did we decide to move away from Kafka, and what was the rationale?"
- "What are the recurring pain points Sarah has raised over our last four 1-on-1s?"
Solving this requires shifting from transcription processing to structured professional memory.
02 — Target Audience & Market Landscape
Ideal Customer Profiles (ICPs)
I prioritized independent knowledge workers who buy productivity software for themselves rather than requiring enterprise procurement:
- Independent Consultants & Advisors: Managing 4–8 enterprise clients concurrently. Their commercial value depends on remembering every client stakeholder's constraints and priorities.
- Fractional Executives (CTOs, CMOs, CPOs): Embedding into multiple executive teams part-time. Need instant context recovery before stepping into strategic reviews.
- Solo Technical Founders & Agency Leads: Interfacing with early customers, investors, and contractors while maintaining high execution speed.
Competitor Landscape & Differentiation
Competitor capabilities and pricing verified from public product documentation and pricing pages as of October 2026.
| Dimension | Granola | Fireflies.ai | Fathom | ProfMe (This Project) |
|---|---|---|---|---|
| Primary Positioning | AI notepad for personal meetings | Enterprise conversation intelligence | Instant post-call video summaries | Longitudinal professional memory graph |
| Capture Method | Local system audio (no bot) | Calendar bot joins call | Zoom/Meet/Teams bot | Local system audio & sealed bundles (no bot) |
| Data Model | Per-meeting notes & templates | Transcript search & CRM sync | Transcript video clips & summaries | Entity graph with explicit lifecycle & state transitions |
| Grounding & Provenance | Scratchpad + transcript fusion | Transcript text search | Timestamped video links | Staged extraction with verbatim quotes & source session links |
| Conflict & Supersession | Overwrites or creates new notes | Appends meeting records | Appends meeting records | Deterministic resolution: CREATE, UPDATE, MERGE, CONTRADICT |
| Pricing | Free (30-day history); $14/user/mo | Pro: $10/mo; Business: $19/mo | Free tier; Premium: $16–$20/mo | Targeted design partner pricing ($18–$24/mo) |
Market Sizing Framework (Bottom-Up)
Rather than citing multi-billion dollar general AI market forecasts, I evaluated the addressable opportunity using a bottom-up model:
- Target Reachable Population: ~4.2M independent knowledge professionals in the US, UK, and Western Europe managing 5+ concurrent client relationships (freelance consultants, fractional leaders, boutique advisory partners).
- Serviceable Addressable Market (SAM): Tech-forward early adopters already paying for premium software tools like Superhuman, Notion, or Claude (~15% = 630,000 professionals).
- Early Serviceable Obtainable Market (SOM): Initial validation cohort of 2,000 to 5,000 paid design partners at $19/month ($228/year ARR), representing a focused $450K–$1.14M initial ARR target.
03 — Product Strategy & Strategic Decisions
Product Pivot: Professional Memory Over Communication Coaching
ADR 022 · Strategic PivotProject Persona was originally conceived around communication coaching (delivery patterns, speaking pace, executive presence scoring). Although the underlying systems architecture was robust, customer discovery revealed a fundamental truth: coaching requires rich, trusted memory to be credible; otherwise, it is indistinguishable from a generic LLM prompt. I pivoted the product to make Professional Memory the primary value proposition, moving coaching to a future premium tier.
Candidate Extraction vs. Direct Durable Writes
ADR 039 · Data IntegrityExtraction outputs are strictly treated as untrusted candidates. A deterministic resolution engine compares candidates against the existing graph to emit explicit MemoryOperation records (CREATE, UPDATE, MERGE, CONTRADICT, DEPRECATE). The user interface presents a clear memory delta: "7 new facts · 2 commitments updated · 1 contradiction flagged."
04 — System Architecture
The ProfMe platform is structured as an event-driven, local-first capture and cloud-orchestrated processing engine:
  Desktop Client (Electron + React)
     │
     ├── 1. Local Audio Capture (CoreAudio / WASAPI system stream)
     ├── 2. Bundle Sealer (Local audio archive + checksum verification)
     └── 3. Resumable Multipart Uploader (Direct to Google Cloud Storage)
                │
                │ Signed GCS URL
                ▼
  Cloud Storage (GCS Bucket) ◄──────── Cloudflare Edge (Reverse Proxy)
                │                                    │
                │ ArtifactUploaded Event             │ REST API
                ▼                                    ▼
  FastAPI Backend (persona-backend)
     ├── Clerk JWT / Workspace Context Validation
     ├── WorkJob Dispatcher
     └── Temporal Client
                │
                ▼
  Temporal Workflow Cluster (persona-work-jobs queue)
     └── MeetingProcessingWorkflow
           ├── Activity 1: SealAudioActivity
           ├── Activity 2: TranscribeSessionActivity (Speech Gateway)
           ├── Activity 3: Staged Memory Extraction (ADR 029)
           │     ├── Call 1: Atomic Fact Extraction (Speaker-turn chunking)
           │     ├── Call 2: Typed Memory Extraction (Facts only -> Entities)
           │     └── Call 3: Title & Summary Generation
           ├── Activity 4: Memory Resolution (ADR 039 -> MemoryOperations)
           ├── Activity 5: IndexMeetingSearchActivity
           └── Activity 6: MarkMeetingReadyActivity
                │
                ▼
  Professional Memory Domain Engine (packages/professional-memory)
     ├── PostgreSQL + pgvector (768-dim embeddings, tsvector FTS)
     ├── Reciprocal Rank Fusion (RRF) Retrieval Pipeline
     ├── Bounded Relationship Expansion (0-hop, 1-hop, max 2-hop)
     └── Evidence Score Threshold Gate (min_evidence_score = 0.40)
Key Architectural Boundaries
- Local-First Audio Sealing: Audio is captured natively on the user's workstation. If the network drops mid-meeting, the recording is preserved locally and uploaded via chunked multipart transfer once connectivity recovers.
- Durable Temporal Workflows: Every meeting ingestion executes as an idempotent Temporal workflow (
meeting-processing-{session_id}). Activities have discrete retry policies, allowing transcription failures or rate limits to recover without re-uploading audio or duplicating downstream records. - Dual Storage Adapters: Domain logic in
persona-professional-memoryinterfaces through a clean repository contract. Development and local testing run against SQLite, while server-side indexing and semantic search run against PostgreSQL with pgvector.
05 — Deep Engineering Challenges
Preventing Prompt Contamination & Hallucinated Entity Promotion
The Problem & Root Cause
Engineering Lesson
Hybrid Retrieval Optimization: Solving the Acronym vs. Paraphrase Dilemma
The Problem & Root Cause
Engineering Lesson
Durable Processing & Idempotent Failure Recovery in Long-Running Workflows
The Problem & Root Cause
Engineering Lesson
06 — Testing, Verification & Security Boundaries
Security and data isolation verified through local test suites in apps/backend/tests/test_document_security.py.
Multi-Tenant Data Isolation
In a professional intelligence product, cross-workspace data leakage is catastrophic. I designed and tested strict boundary enforcement:
- Workspace Scoping: Every memory entity, search index, and artifact record is foreign-keyed to a verified
workspace_id. - Query Scoping: The repository layer enforces workspace parameterization at the SQL AST level; no un-scoped queries can execute.
- Security Test Verification: Local automated security suites verify:
- Cross-workspace retrieval isolation (User in Workspace A cannot access Workspace B entities under any query parameter).
- Deleted-document exclusion (Soft-deleted records are immediately scrubbed from search query plans).
- Malicious parser rejection (Malformed or adversarial audio payloads are rejected at upload validation without crashing workers).
07 — Business Model & Go-to-Market Strategy
Monetization Model
- Target Tier: High-value individual subscription model at $18–$24 / user / month (billed annually).
- Positioning: Priced above consumer transcription utilities ($10/mo) but below enterprise sales-intelligence platforms ($39/mo), aligned with high-income independent consultants and fractional executives who easily expense software under business productivity.
- Value Metric: Unlimited meeting memory extraction, persistent entity graph, and fast context recovery.
Customer Acquisition Strategy
- Direct Founder & Consultant Outreach: Hand-onboarding initial design partners through structured pilot programs.
- GrowthStory Educational Content: Technical teardowns on RAG architecture, agent reliability, and context management establishing technical authority.
- Product-Led Loops: Meeting follow-up summaries and prep sheets generated with clean source citations that shared attendees observe and ask about.
08 — Engineering Lessons & Future Priorities
- Memory is an entity graph problem, not a text generation problem. Building useful AI products requires structuring data into relationships, lifecycles, and provenance rather than relying on LLMs to re-read gigabytes of unstructured text on every turn.
- Abstention is a feature. The difference between a prototype and a production AI system is knowing when to say "insufficient evidence" rather than guessing.
- Next Technical Priorities:
- Implement live meeting audio streaming with low-latency chunked transcription.
- Expand input connectors beyond audio to include Slack channel discussions and Notion knowledge bases.
- Ship multi-tenant team memory sharing with granular role-based visibility controls (ADR 041).
09 — Related Case Studies & Technical Writing
Building an AI Product with Retrieval, Agents, or Complex Workflows?
I partner with founders and engineering leaders to design grounded retrieval systems (RAG), durable multi-step workflows, and reliable AI architectures that hold up under real-world ambiguity.
Satish Rajnale
Senior AI Product Engineer · Full-Stack & Systems Architect
I help early-stage founders and engineering teams build reliable AI products, production-ready full-stack applications, and durable backend architectures. My focus is on the complete delivery lifecycle: from customer discovery and system design to robust implementation, evaluation, and release.
Related Technical Articles
Designing Memory for AI Agents: Working Context, PostgreSQL, RAG, and Long-Term State
How I design context layers — working memory, canonical state, retrieval, and provenance — so AI features stay useful as products grow.
AI ProductEvaluating AI Agents in Production: Golden Datasets, Human Review, and Release Gates
A practical playbook for offline evals, online acceptance metrics, HITL boundaries, and tightening autonomy only when the product earns it.
AI SystemsFault-Tolerant AI Agents: Retries, Checkpointing, Idempotency, and Durable Workflows
Designing durable AI workflows with checkpoints, idempotent tools, Temporal-style recovery, and human takeover — so partial failure does not become silent corruption.