Sovereign Intelligence
Architectural Thesis & R&D · User-Owned Intelligence, Trust Boundaries & Provenance
An architectural research framework exploring trustworthy AI systems built around user data sovereignty, multi-tiered trust boundaries, verifiable evidence lineage, and reversible human-in-the-loop proposals.
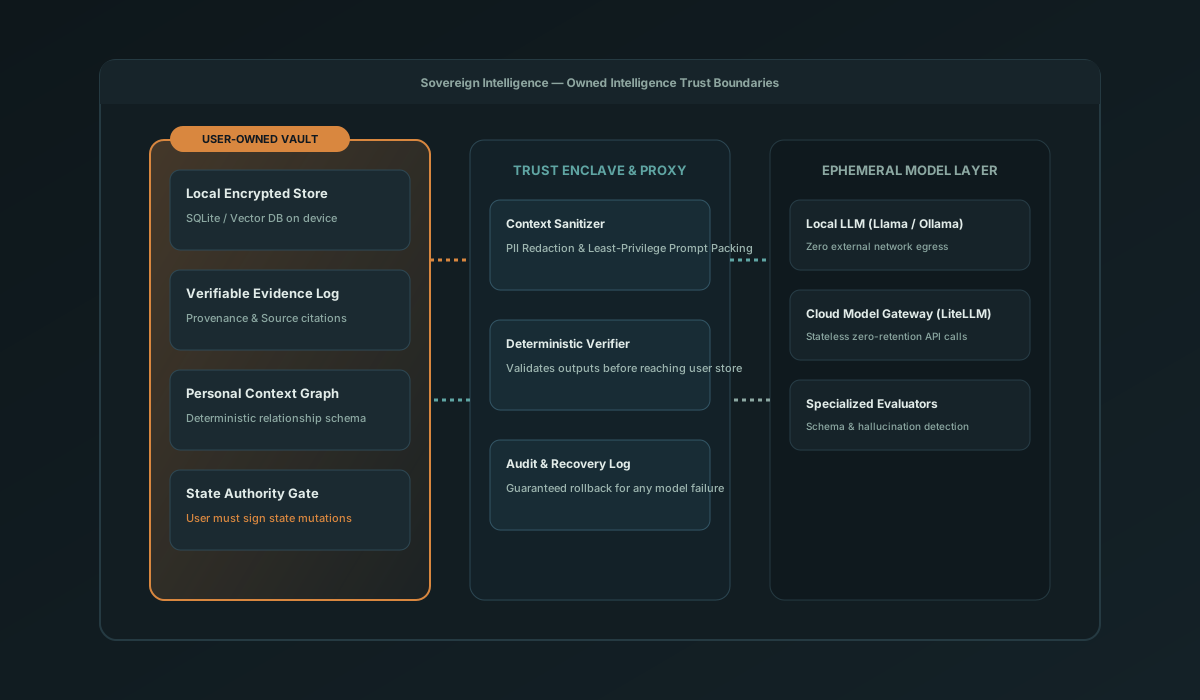
Table of Contents
- 01 — The Core Problem: The Epistemological Hazard of Generative AI
- 02 — The Sovereign Intelligence Architectural Framework
- 03 — Key Architectural Principles & Hypotheses
- 04 — Practical Impact on Shipped Systems
- 05 — Trade-Off Analysis & Architectural Open Questions
- Open Research Questions
- 06 — Relevance to Engineering Engagements
- 07 — Related Case Studies & Technical Writing
The prevailing architecture of generative AI products relies on centralized cloud aggregation: users send their private context, conversations, and records to proprietary model APIs, receiving transient, ephemeral chat responses in return.
This pattern presents three structural vulnerabilities for software products:
- Loss of Epistemic Sovereignty: Users lose control over what constitutes truth. Model hallucinations, biased summaries, or stale assumptions blend invisibly into the user's permanent records.
- Provider Lock-In & Privacy Exposure: Personal and enterprise context is fragmented across closed cloud silos, exposing sensitive data to model retraining and making provider switching prohibitive.
- Unbounded Agentic Risk: Autonomous AI agents that execute irreversible actions without human verification create catastrophic failure modes.
Sovereign Intelligence is an architectural research thesis designed to answer the fundamental question:
"How do we build an AI-native intelligence layer that continuously compounds contextual knowledge while ensuring the individual retains unconditional ownership of their data, full auditability of AI reasoning, and final authority over all actions?"
This project represents foundational systems architecture research and R&D. It is not presented as a commercially shipped SaaS application.
01 — The Core Problem: The Epistemological Hazard of Generative AI
In traditional AI software architectures, the data flow is linear and ungrounded:
User Input ──► Cloud AI Model ──► Unvalidated Response ──► Database Mutation
When an LLM produces a response that mixes 80% factual observation with 20% plausible hallucination, traditional software treats the entire payload as authoritative application state. Over weeks of usage, these small hallucinations compound, polluting the database until the user can no longer distinguish real historical events from model fabrications.
To build trustworthy software, systems must treat AI models not as authoritative databases, but as probabilistic interpretation engines bounded by strict epistemological gates.
02 — The Sovereign Intelligence Architectural Framework
I designed a 6-level trust boundary that physically separates objective reality from AI interpretation:
  Level 1: Objective Reality (Evidence)
    └── Immutable captures: audio recordings, raw notes, sensor signals, timestamped quotes
               │
               ▼
  Level 2: Canonical State (Human Facts)
    └── Validated user records: calendar events, verified tasks, explicit human edits
               │
               ▼
  Level 3: Derived Intelligence (AI Interpretation)
    └── Probabilistic extractions: entity links, patterns, suggested topics
        * MUST carry full provenance (source ref, confidence score, model id)
        * NEVER directly overwrites Level 2 state
               │
               ▼
  Level 4: AI Reasoning & Proposal Engine
    └── Multi-model reasoning (Local SLM for privacy, Cloud LLM via proxy)
    └── Generates candidate actions with rationale and source citations
               │
               ▼
  Level 5: Human Approval Gate
    └── Explicit user confirmation (Approve / Reject / Edit)
               │
               ▼
  Level 6: Bounded Execution
    └── Deterministic execution of approved actions with full rollback audit
03 — Key Architectural Principles & Hypotheses
Epistemological Separation of Truth
Principle 01 · Data ModelThe architecture defines three distinct data classes:
- Evidence: Verbatim records of what actually happened (e.g., meeting audio bytes, raw meeting transcripts, unchanged document files).
- Inferences: What an AI model hypothesizes those facts mean (e.g., extracted commitments, suggested project tags). Inferences are ephemeral and re-computable.
- Canonical State: The agreed state of the world confirmed by the human user. Inferences can only graduate to Canonical State through explicit validation.
Multi-Model Routing with Local-First Privacy Boundaries
Principle 02 · InfrastructureThe framework establishes a two-tier inference topology:
- Tier 1 (On-Device Local SLMs): Small language models running locally (e.g., quantized Llama, Gemma, or Apple on-device models) handle sensitive entity extraction, PII scrubbing, and local vector indexing with zero data leakage.
- Tier 2 (Cloud LLMs via Audited Proxy): High-parameter cloud models (Claude 3.5 Sonnet, GPT-4o, Gemini 1.5 Pro) are invoked only for complex synthesis, with PII redacted and requests routed through an auditable, credential-isolated proxy.
Proposals Over Autonomous Execution
Principle 03 · Safety & AgencyAI systems should optimize for proposing reversible actions rather than autonomous execution. The system presents candidate diffs: "Here is the draft response and calendar invite based on July 2 notes. Approve, edit, or discard?"
04 — Practical Impact on Shipped Systems
While Sovereign Intelligence originated as a research thesis, its principles served as the architectural foundation for my concrete, implemented products:
- ProfMe (Longitudinal Professional Memory):
- Directly implemented the Level 1 vs. Level 3 separation in ADR 025 (Memory Provenance & Lifecycle): every commitment carries a
MemoryProvenancestruct linking back to transcript timestamps and model confidence. - Implemented the Level 4 proposal gate in ADR 039 (Memory Resolution): LLM outputs are treated as unconfirmed candidates; a deterministic resolution engine emits
MemoryOperationrecords (CREATE,UPDATE,CONTRADICT) for human review.
- Directly implemented the Level 1 vs. Level 3 separation in ADR 025 (Memory Provenance & Lifecycle): every commitment carries a
- PrimeLife OS (Local-First Personal Intelligence):
- Implemented Tier 1 data sovereignty: personal journal entries, habits, and energy logs write directly to a local SQLite database on the user's machine.
- Decoupled model inference into asynchronous
ai_jobs, ensuring provider outages never jeopardize local source data.
05 — Trade-Off Analysis & Architectural Open Questions
| Architectural Dimension | Centralized Cloud AI | Sovereign Intelligence Framework |
|---|---|---|
| Data Sovereignty | Proprietary vendor cloud | User-owned local database or private cloud |
| Model Portability | High vendor lock-in | Complete model independence via abstraction layer |
| Offline Functionality | Non-existent (Requires continuous connection) | Full read/write autonomy on client |
| Failure Blast Radius | Provider outage freezes entire application | Cloud failure delays AI enrichment; core data is unaffected |
| Engineering Overhead | Low (Simple REST API calls) | High (Requires local sync queues, provenance schemas, RRF) |
Open Research Questions
- Local Model Quality vs. Battery/Thermal Limits: On mobile devices, running local SLMs for real-time extraction introduces battery drain and thermal throttling. Evaluating quantized model performance on Apple Neural Engine vs. background server proxying remains an active area of investigation.
- Cryptographic Evidence Verification: Exploring content-addressable storage (hashes of audio recordings) to make evidence tampering mathematically impossible.
06 — Relevance to Engineering Engagements
For founders and technical teams building modern software, the Sovereign Intelligence framework provides a practical roadmap:
- Enterprise Readiness: How to build AI systems that enterprise CISOs and compliance officers will actually approve, by maintaining clear data boundaries and audit trails.
- Hallucination Containment: How to stop AI errors from corrupting product databases and destroying customer trust.
- Provider Resilience: How to design systems that can seamlessly switch between OpenAI, Anthropic, Google, and open-source models as pricing and capabilities evolve.
07 — Related Case Studies & Technical Writing
Need Architectural Guidance on Trust Boundaries and Multi-Model AI?
I help teams design AI systems with clear data provenance, multi-model routing, and human-in-the-loop safeguards that prevent model hallucinations from corrupting business state.
Satish Rajnale
Senior AI Product Engineer · Full-Stack & Systems Architect
I help early-stage founders and engineering teams build reliable AI products, production-ready full-stack applications, and durable backend architectures. My focus is on the complete delivery lifecycle: from customer discovery and system design to robust implementation, evaluation, and release.
Related Technical Articles
Designing Memory for AI Agents: Working Context, PostgreSQL, RAG, and Long-Term State
How I design context layers — working memory, canonical state, retrieval, and provenance — so AI features stay useful as products grow.
AI ProductEvaluating AI Agents in Production: Golden Datasets, Human Review, and Release Gates
A practical playbook for offline evals, online acceptance metrics, HITL boundaries, and tightening autonomy only when the product earns it.