AI Agents
How to Build Reliable AI Agents in Production: Architecture, Tools, State, and Evaluation
A practical system design for bounded tool use, durable state, human approval, and measurable outcomes in AI products.
On this page
- Start with the job, not the framework
- Capability vs limitation design
- Architecture that survives contact with reality
- Why graphs beat free-form “ReAct forever”
- Make the tool boundary explicit
- Tools are product surfaces
- Memory is not a vector dump
- Evaluation is part of shipping
- Post-deploy ownership
- What I’d tell my past self
- A worked example from professional-memory processing
- Limits and further reading
Most “AI agent” demos fail the moment a real customer asks for something boring and important: reliably extract commitments from this meeting and put them where my team already works. That sentence is not a prompt problem. It is a product system problem.
This is an engineering pattern guide, not a benchmark report or a claim that every example below is deployed as shown. It draws on the product and architecture concerns represented in my published work: meeting → evidence → memory → action, bounded research, and durable workflow orchestration.
An agent is not “an LLM that can use tools.” A production agent is a constrained product surface: goals, permissions, state, recovery, and a clear definition of done that a human would accept.
Start with the job, not the framework
When someone says “build an agent,” I translate it into three questions:
- What outcome must be true in the user’s world? (task created, report delivered, CRM updated, draft ready for review)
- What evidence is allowed? (transcript, email, Notion, browser, APIs)
- Where is autonomy earned vs assumed? (auto-run vs propose-and-approve)
If you cannot answer those without naming LangGraph, CrewAI, or a model vendor, you are not ready to pick an architecture. Frameworks amplify clarity; they cannot invent it.
A useful product framing:
- Trigger — calendar end, webhook, button, schedule
- Understand — normalize input into structured intent
- Act — tools with schemas and side-effect boundaries
- Verify — schema validation, evals, human review
- Persist — write durable state the next run can trust
That loop is what customers buy. The model is one component inside it.
Capability vs limitation design
AI product engineering is mostly constraint design. Models are probabilistic, context windows are finite, tools fail, and users will blame the product for silent wrongness.
Before I expand autonomy, I write a short capability contract:
| Capability | Honest limit | Product response |
|---|---|---|
| Extract decisions from meetings | Misses nuance, invents owners | Require evidence spans + HITL for commitments |
| Research a topic | Stale or conflicting sources | Cite sources; prefer synthesis over certainty |
| Update CRM | Destructive side effects | Propose diffs; never silent overwrite |
| Multi-step planning | Drift and loops | Hard budgets, checkpoints, max tool calls |
This is the difference between a demo and a product. Customers do not need infinite agent magic. They need predictable behavior when the model is wrong.
Architecture that survives contact with reality
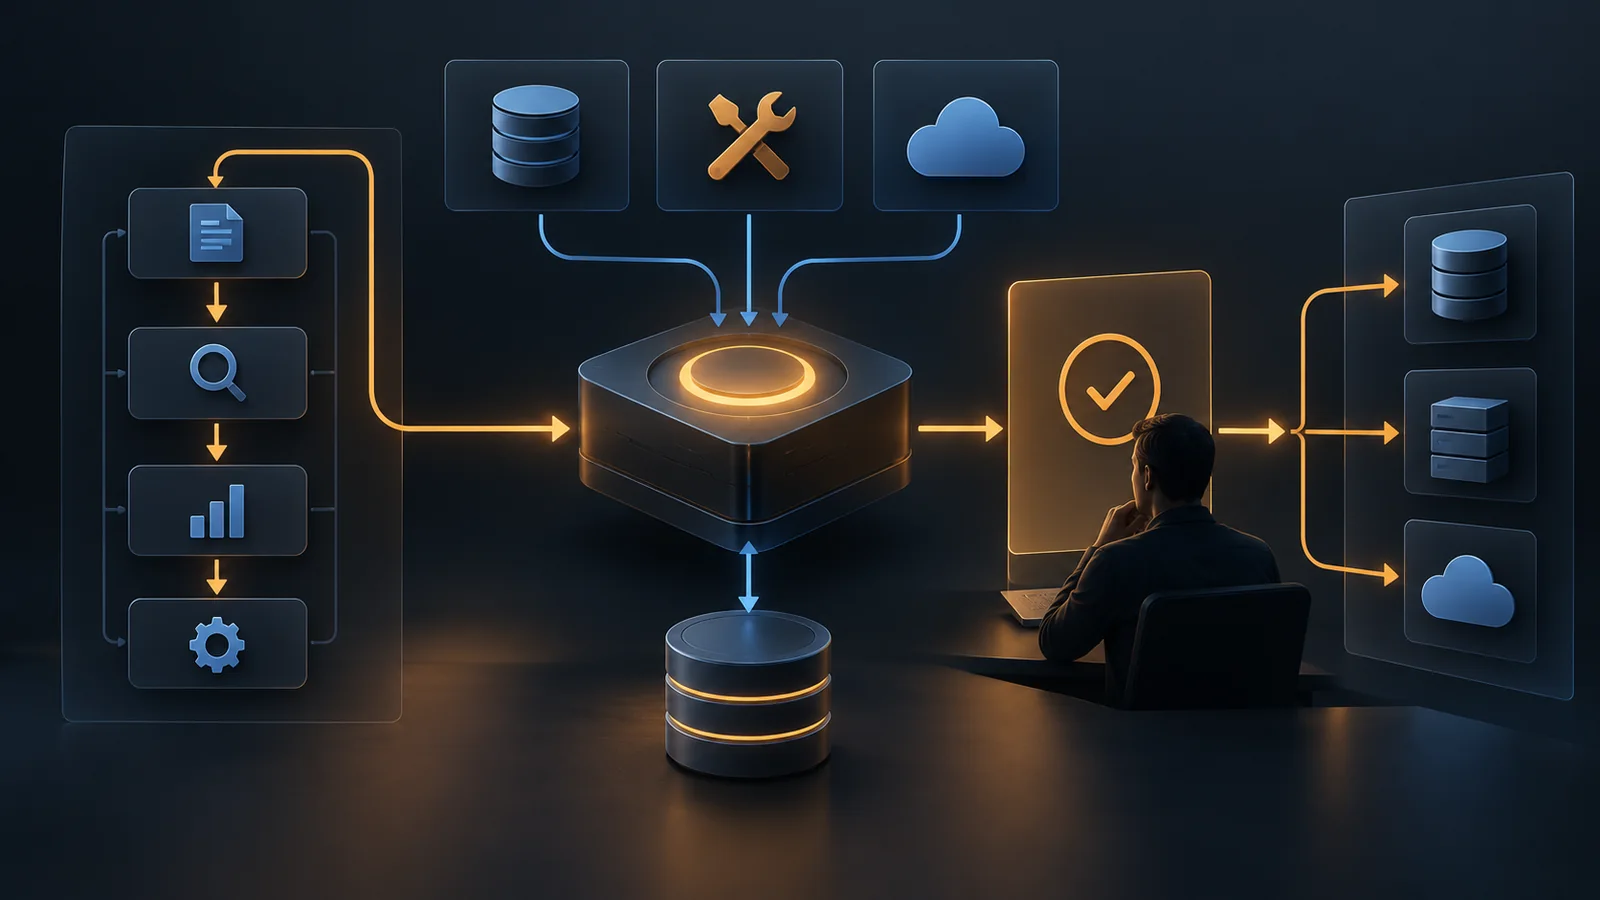
For systems that must run longer than a single request, I prefer an explicit state machine (LangGraph-style graphs, Temporal workflows, or a hybrid):
Goal
  → Plan (bounded)
  → Tool step
  → Observe / validate
  → Update canonical state
  → Checkpoint
  → Continue or stop for human review
Why graphs beat free-form “ReAct forever”
Unstructured agent loops are great for exploration and terrible for operations. In production you need:
- Inspectable state — what did we believe before the crash?
- Idempotent tools — retries must not double-create tasks
- Budgets — tokens, time, tool calls, dollars
- Terminal conditions — success, blocked, needs_human, failed
A minimal mental model in TypeScript-shaped pseudocode:
type AgentState = {
  goal: string;
  evidence: Evidence[];
  draft: StructuredOutput | null;
  status: "running" | "needs_review" | "done" | "failed";
  budget: { tokens: number; toolCalls: number };
};

async function step(state: AgentState): Promise<AgentState> {
  if (state.budget.toolCalls <= 0) return { ...state, status: "needs_review" };

  const action = await planner.select(state);
  const observation = await tools.run(action); // schema-validated
  const next = await reducer(state, observation);

  return checkpoint(next);
}
The important part is not the library. It is planner → tool → validate → reduce → checkpoint.
The tool result should preserve the difference between “no matching record” and “the dependency failed.” A reducer can then make a deterministic transition instead of asking the model to infer what an exception means:
type ToolResult<T> =
  | { kind: "ok"; value: T; evidenceIds: string[] }
  | { kind: "retryable_error"; code: string; retryAfterMs?: number }
  | { kind: "terminal_error"; code: string };
This is an interface sketch, not a framework API. Keep raw exception text out of model-visible observations, and make authorization failures terminal for that action. A retry policy belongs to the orchestrator; a permission decision belongs to trusted application code.
Make the tool boundary explicit
Treat a model-generated tool call as untrusted input. Validate its arguments, bind it to the authenticated user and tenant on the server, and return a typed result that distinguishes a valid empty result from a failed request. Do not let the model choose tenant IDs, authorization scopes, or arbitrary URLs.
For example, the application layer can reduce a proposed action before it reaches an integration:
def validate_create_task(proposal: dict, actor: Actor) -> CreateTask:
    task = CreateTask.model_validate(proposal)
    if task.owner_id not in actor.assignable_owner_ids:
        raise PermissionError("Owner is outside the actor's allowed scope")
    if not task.evidence_ids:
        raise ValueError("A task proposal needs supporting evidence")
    return task
This is illustrative Python, not code copied from a deployed project. Production authorization should come from trusted application state; a schema alone does not grant permission.
Tools are product surfaces
Weak tool schemas create hallucination. Strong schemas create leverage.
Practices that paid off:
- Describe tools like API docs for a junior engineer: purpose, when not to use, exact args, failure modes.
- Prefer small tools with clear side effects over mega-tools that “do CRM.”
- Return structured observations (JSON) the reducer can merge, not prose blobs.
- Separate read tools from write tools. Writes often require HITL.
If a tool can mutate customer data, treat the agent as untrusted until a human or a deterministic policy approves the mutation.
Memory is not a vector dump
Agents fail when “memory” means “stuff everything into the prompt.” Production memory is layered:
- Working memory — current goal, plan, last N observations
- Episode memory — this run’s artifacts and decisions
- Canonical product state — Postgres rows the business trusts
- Retrieval — RAG over evidence with provenance
In professional intelligence products, I keep a hard line: models propose; databases decide what is true. Derived intelligence links back to evidence. That single decision prevents agents from quietly rewriting reality.
Evaluation is part of shipping
You cannot A/B your way out of agent chaos without golden tasks. My minimum bar before expanding autonomy:
- A labeled set of inputs → expected structured outputs
- Scoring for schema validity, citation presence, and critical field accuracy
- Regression runs on every prompt or tool change
- Online monitoring: failure rate, human rejection rate, cost per successful outcome
Offline evals catch silly breaks. Online signals catch the product truth: are humans accepting the agent’s work?
Post-deploy ownership
Shipping an agent is the start of product engineering, not the end. After deploy I watch:
- Where humans override the agent (those are your next design constraints)
- Which tools fail most (timeouts, auth, empty search)
- Cost spikes from loops or oversized context
- “Looks right but isn’t” complaints — the most dangerous class
The ownership loop looks like:
telemetry → cluster failures → tighten schema or reduce autonomy → re-eval → ship
That is 0→1 AI product work. Framework choice is secondary.
What I’d tell my past self
- Don’t start with multi-agent swarms. Start with one reliable workflow and a clear verify step.
- Spend more time on state and side-effect boundaries than on clever prompts.
- Make human review a first-class status, not an apology UI.
- Optimize for accepted outcomes per dollar, not tokens per second.
- Write the capability contract before you write the agent graph.
Agents are having a moment because models got better. Products win because someone owns the boring path from customer request to durable result — including the week after launch when reality shows up.
If you are building something similar and want a partner who will own that loop end to end, that is the work I care about most.
A worked example from professional-memory processing
The ProfMe source case study gives one concrete example of the boundaries above. Its meeting workflow is a sequence of named processing activities; the professional-memory package owns ingestion and query behavior; the storage adapters provide SQLite and PostgreSQL implementations. Temporal coordinates the longer-running work. That layout means the agent is one stage in a product pipeline, not the whole application.
meeting audio / transcript
          │
          ▼
capture → transcription → named enrichment activities
                                  │
                                  ▼
                    validated extraction candidates
                                  │
                                  ▼
                  professional-memory ingestion API
                                  │
                   ┌──────────────┴─────────────┐
                   ▼                            ▼
            source evidence               derived memory
                   └──────────────┬─────────────┘
                                  ▼
                     retrieval and human review
The key decision is to retain the relationship between a candidate memory and the source session or transcript reference. A model can propose a commitment, but downstream product code still needs to validate its shape, attach provenance, apply workspace scope, and expose an appropriate review state. The implementation also uses bounded workflow activities and explicit retry policies; those policies help with transient failures, but they do not replace idempotent writes or reconciliation.
This example changes how I evaluate “agent quality.” I ask whether the surrounding system can explain where a result came from, recover a failed step, and avoid turning an uncertain extraction into an irreversible action. The repository’s local retrieval report uses synthetic fixtures and does not measure end-to-end answer faithfulness, so it is evidence about a narrow retrieval path, not a blanket quality score for the product.
Limits and further reading
There is no universal agent architecture. A single deterministic workflow is often easier to inspect than a planner loop; a durable workflow engine adds operational concepts that a short request/response feature may not need. Tool schemas, evaluations, and checkpoints reduce classes of risk but do not prove that a model is correct.
Working on a Similar Engineering Challenge?
Building an agent workflow? I can help with tool boundaries, orchestration, state, and release evaluation.
Satish builds AI-native applications, agent workflows, and scalable backend systems across retrieval, orchestration, integrations, product architecture, and reliability.
Related reading
- AI SystemsFault-Tolerant AI Agents: Retries, Checkpointing, Idempotency, and Durable WorkflowsDesigning durable AI workflows with checkpoints, idempotent tools, Temporal-style recovery, and human takeover — so partial failure does not become silent corruption.
- AI ProductEvaluating AI Agents in Production: Golden Datasets, Human Review, and Release GatesA practical playbook for offline evals, online acceptance metrics, HITL boundaries, and tightening autonomy only when the product earns it.